ARTICLE 05
Redis Made the App Faster—But What About Stale Data?
A lesson about caching and the importance of data correctness
October 20, 2026 / 5 min read
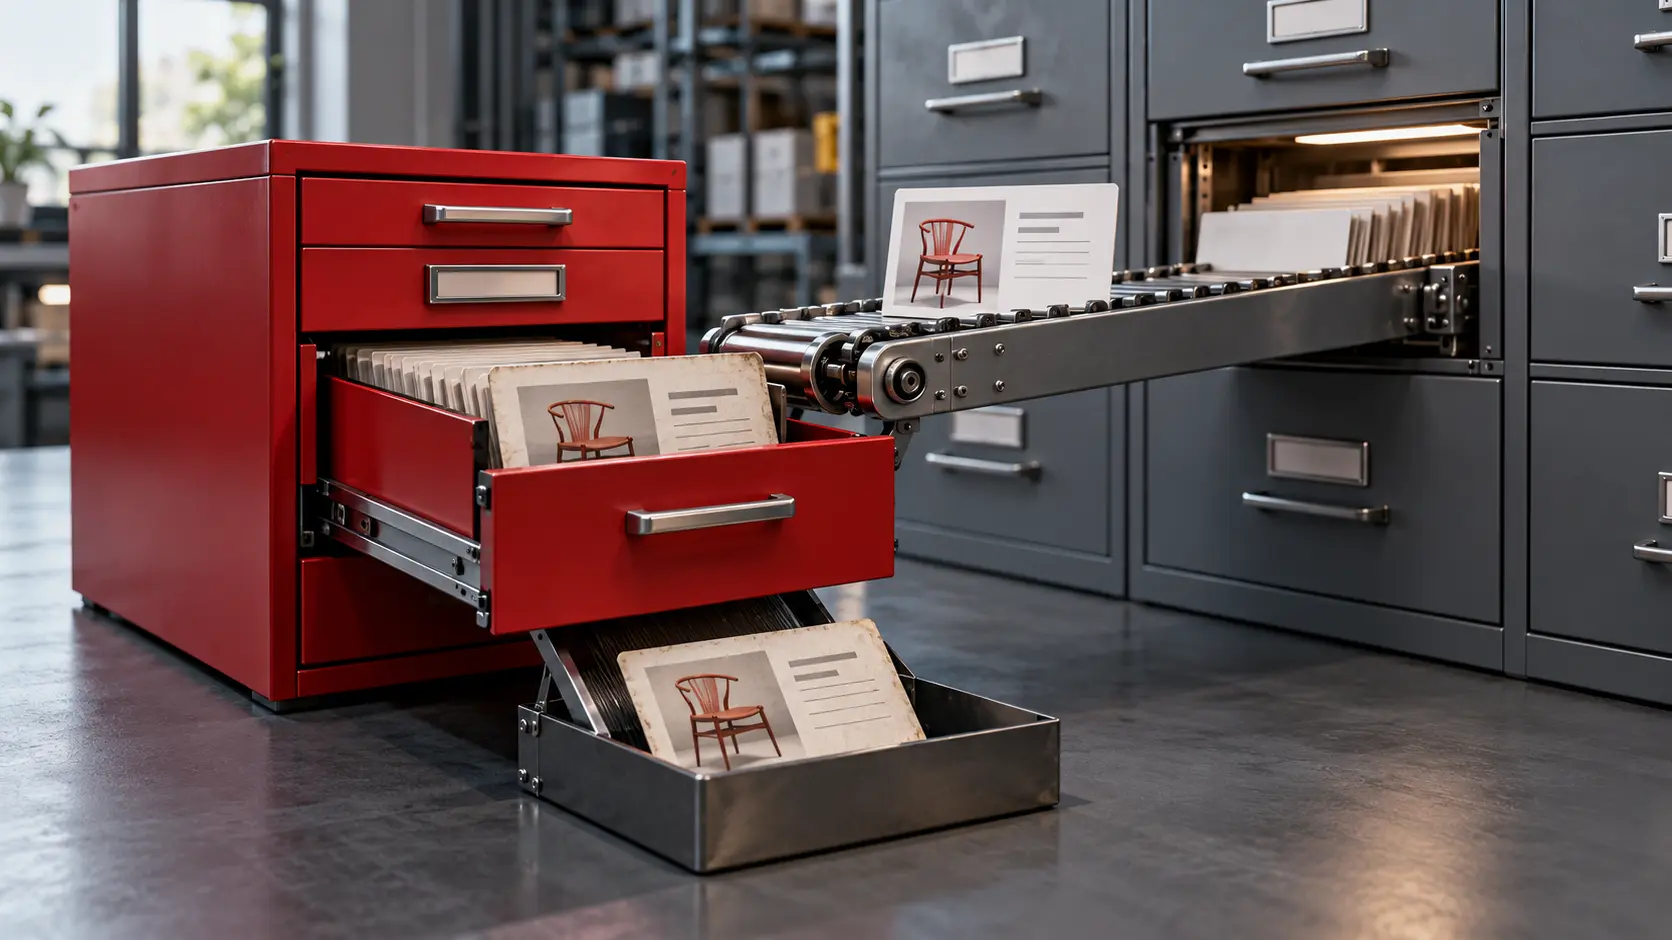
While developing web applications, I started using Redis to improve performance and reduce repeated database queries.
The idea sounds simple: instead of reading from the database on every request, store the result in Redis and retrieve it quickly when needed.
Over time, I realized that the real challenge is not storing data. It is knowing when that data must be updated or removed.
Where is the problem?
Imagine an online store displaying a product priced at 100 SAR.
The product is cached in Redis, and the merchant later changes the price to 80 SAR.
If the application continues reading the old cache entry, customers may still see 100 SAR even though the database has been updated.
This is known as a stale cache.
How do we handle it?
A common strategy is the cache-aside pattern:
- When data is requested, look for it in Redis first.
- If it is missing, read it from the database and cache it for future requests.
- When the data changes, update the database and invalidate the old Redis entry.
- Use an appropriate TTL to limit how long cached data remains valid.
Read path
Write path
Tenant-scoped keys plus a TTL appropriate for the data.
What did I learn?
In a multi-tenant SaaS, cache keys must also include the tenant identity so data from different stores can never be mixed.
Using Redis does not mean caching everything. It means selecting suitable data and defining a clear validity strategy.
Some data can tolerate a short delay before it is refreshed. Sensitive values such as price and inventory at checkout should be verified against a trusted source.
Conclusion
The goal is not simply to build a fast application. It is to build a fast application that provides correct, trustworthy information.
Performance improvements must never come at the expense of data correctness.